Signal Versus Noise: Reclaiming Your SOC From the Alert Avalanche
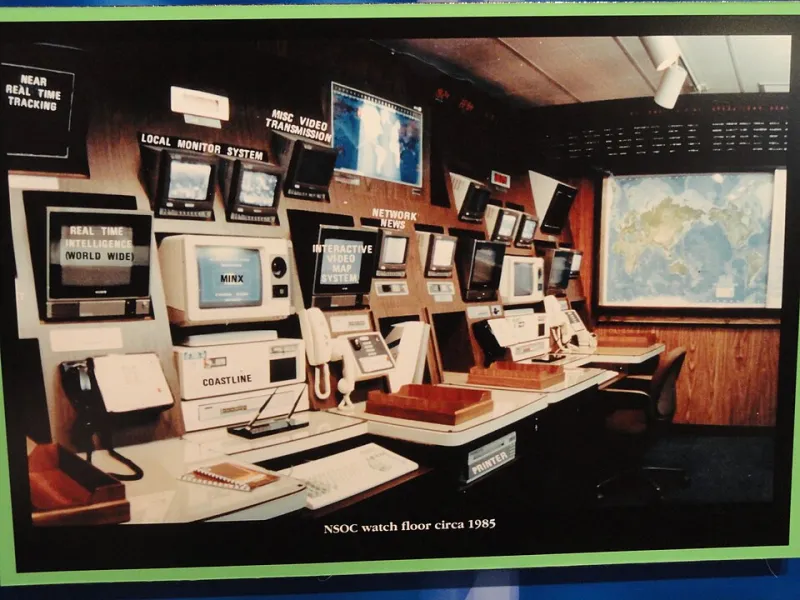
Photo: Daderot, CC0, via Wikimedia Commons
There is a particular kind of exhaustion that sets in around hour six of a twelve-hour SOC shift when the alert queue has not dipped below four hundred items since morning. Analysts stop reading carefully. Triage becomes reflexive. The cognitive shortcuts that accumulate over weeks of sustained overload are not laziness — they are survival. And threat actors know it.
Alert fatigue is one of the most consequential and least discussed vulnerabilities in enterprise security. It does not show up in CVE databases or penetration test reports, but the damage it enables is measurable. According to research from the Ponemon Institute, the average security analyst in a mid-sized US organization investigates fewer than half the alerts generated on any given day. The rest are triaged by heuristic or dismissed outright. Somewhere inside that dismissed remainder, on some days, is a genuine intrusion.
Why Well-Configured SIEMs Still Overwhelm Teams
The instinct when confronted with alert overload is to blame misconfiguration. Tighten the rules, the thinking goes, and the noise will subside. That instinct is not wrong, but it is incomplete. Even organizations that invest heavily in SIEM tuning encounter a structural ceiling — a point at which the sheer scope of modern IT environments generates legitimate detection events faster than human analysts can process them.
Consider the math. A mid-sized enterprise running cloud workloads, SaaS applications, endpoint detection tools, and network monitoring sensors may ingest between five hundred million and five billion log events per day. Even with aggressive filtering, converting that telemetry into actionable alerts at a rate of one alert per ten thousand events produces tens of thousands of daily notifications. No team — regardless of headcount or skill — can respond meaningfully to that volume.
The problem is compounded by default rule sets. Most commercial SIEM platforms ship with detection libraries designed for breadth, not precision. Vendors reasonably err on the side of sensitivity; missing a real threat is far more damaging to their reputation than generating false positives. The result is that organizations deploying out-of-the-box configurations inherit detection logic calibrated for environments that do not resemble their own.
The False Positive Feedback Loop
False positives are not merely an inconvenience — they are a corrupting force within the detection workflow. When analysts repeatedly investigate alerts that resolve as benign, they develop negative associations with specific rule categories. Over time, those categories receive less scrutiny. The rule that cried wolf thirty times gets mentally deprioritized on the thirty-first alert, which may be the one that matters.
This dynamic is not hypothetical. A well-documented 2022 incident at a regional US financial institution revealed that attackers conducting a low-and-slow lateral movement campaign had triggered an authentication anomaly rule seventeen times over a three-week period. Analysts had reviewed — and closed — the first four alerts as expected behavior from a recently onboarded remote employee. The subsequent thirteen were closed without review. The breach was discovered only when a third-party auditor flagged unusual data staging activity during a routine assessment.
The attackers had not found a gap in the detection rules. They had found a gap in human attention, cultivated by months of false positive conditioning.
Tactical Tuning: Reducing Volume Without Reducing Coverage
The path forward is not to generate fewer alerts by removing detection logic — it is to generate fewer meaningless alerts by contextualizing detection logic against the specific environment it monitors.
Establish a baseline before writing rules. Effective SIEM tuning begins with understanding what normal looks like in your environment. User and Entity Behavior Analytics (UEBA) capabilities — whether native to your SIEM or integrated from a third-party platform — can establish behavioral baselines that make anomaly detection significantly more precise. An authentication event at 2:00 a.m. from an account that has never previously authenticated outside business hours is materially different from the same event on an account whose owner regularly works late.
Tier your alert taxonomy. Not all detections warrant the same response urgency. Implementing a structured severity taxonomy — and enforcing it rigorously — allows analysts to batch-process lower-confidence alerts during quieter periods rather than treating every notification as equally time-sensitive. Many organizations find that moving from a three-tier to a five-tier severity model dramatically improves triage efficiency without increasing risk exposure.
Implement alert suppression windows with expiration dates. When a known-benign event pattern generates repeated false positives, the temptation is to create a permanent suppression rule. Resist it. Permanent suppression rules accumulate silently and eventually cover detection logic that should still be active. Build suppression windows with mandatory review dates — typically thirty to ninety days — so that environmental changes do not quietly disable detection coverage.
Correlate before alerting. Single-event detections are inherently noisy. Detection logic that requires multiple correlated indicators — for example, a failed authentication followed by a successful one from a new geolocation, followed by privilege escalation activity — generates far fewer alerts and far higher fidelity. Investing in correlation rule development is time-consuming, but the operational return is substantial.
The 60-80% Reduction: What It Actually Takes
Organizations that achieve dramatic reductions in alert volume — the kind measured in percentage points rather than marginal improvement — typically share several characteristics. They treat SIEM tuning as a continuous operational discipline rather than a one-time deployment task. They assign dedicated ownership for detection engineering, separate from the analysts responsible for responding to alerts. And they measure outcomes: tracking false positive rates, mean time to triage, and analyst escalation rates as operational KPIs alongside traditional security metrics.
A large US healthcare network that undertook a systematic tuning initiative reported reducing daily alert volume by seventy-three percent over an eighteen-month period. Critically, their detection rate for confirmed security incidents increased during the same period. The reduction came almost entirely from eliminating redundant rules, suppressing known-benign event patterns, and implementing correlation logic that replaced individual event alerts with consolidated incident summaries.
The investment required was not trivial. Two dedicated detection engineers, a twelve-month engagement with a managed security services provider for baseline assessment, and a significant internal training commitment for SOC analysts. But the alternative — continuing to operate a team in a state of perpetual cognitive overload — carried its own costs, both in staff attrition and in the incidents that were missed.
Structural Recommendations for Security Leaders
For security operations leaders evaluating their current SIEM posture, the following priorities are worth immediate attention. Conduct a formal false positive audit — categorize your top twenty alert-generating rules by confirmed incident rate and suppress or retune any rule producing fewer than five percent confirmed positives. Evaluate whether your current SIEM platform supports the correlation and behavioral analytics capabilities your environment requires; many organizations are running platforms that predate the cloud-scale environments they now need to monitor. And invest in detection engineering as a distinct function within your security organization, staffed by individuals whose primary accountability is the quality of the detection pipeline rather than the volume of alerts processed.
The adversary community has understood for years that overwhelming defenders is a viable strategy. Engineering precision into your detection infrastructure is not a technical optimization — it is a direct countermeasure to one of the most effective tactics in the modern threat actor playbook.